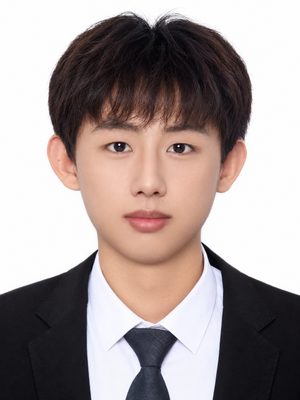
Jinyang Wang (王金阳)Master's Student
Institute of Automation, Chinese Academy of Sciences (CASIA) |
|
Short Bio
I am a Master's student at the Institute of Automation, Chinese Academy of Sciences (CASIA), majoring in Pattern Recognition and Intelligent Systems. I received my B.Eng. degree in Automation from the University of Science and Technology Beijing (USTB) in 2025.
My research focuses on Autonomous Driving, World Models, Reinforcement Learning, and Embodied AI.
News
- 2026.09: Our work SV-WAM is available on arXiv.
- 2026.07: Finished my internship at Changan Auto, working on autonomous-driving world models.
- 2025.09: Started my Master's study at CASIA.
- 2025.06: Finished my robot-vision research internship at CASIA.
Internship
Autonomous Driving Algorithm Intern · Wan2.1 DiT · 6-Camera Video Generation · RGB-LiDAR Streaming
- Multi-view video generation. Owned the six-camera branch of a pose-controllable driving world model based on Wan2.1 DiT, extending the data pipeline, unified latent layout, and synchronized surround-view generation; designed ring-style local Cross-View Attention, reducing allowed cross-view Q-K connections by 50%.
- Geometric consistency. Designed a front-view Plücker Ray Map and Epipolar-Masked Attention for cross-view and RGB-LiDAR token interaction, improving VSC from 0.771 to 0.830 and reducing DAS from 2.41 m to 2.19 m.
- Long-context training. Adapted 24-way Attention Sequence Parallel, view-sharded VAE encoding, latent-level aggregation, and pre-sharded Plücker conditioning, increasing the maximum training length from 113 to 381 frames.
- Real-time world generation. Contributed to the DMD Distillation, Self-Forcing, and Temporal-Decay KV Cache pipeline, helping the system reach approximately 10 Hz RGB-LiDAR streaming generation with long-horizon rollouts beyond 240 frames.
Vision-Language Navigation · 3D Reconstruction · Robot Deployment
- Built a generative world-model-driven navigation pipeline from natural-language instruction → target-scene generation → trajectory recovery → real-observation refinement, combining LLM and world-model priors for robot goal localization and navigation decision making.
- Reproduced and integrated DUSt3R and VGGT for multi-view reconstruction, including camera-pose estimation, dense point-cloud reconstruction, and scale calibration; completed 500+ image-processing annotations and participated in embedded deployment and unmanned-robot system integration.
Selected Publications
SV-WAM: An Efficient Surround-View World-Action Model for End-to-End Autonomous Driving
Jinyang Wang, Shiwei Li, Junjian Wang, et al.
arXiv preprint, 2026.
An efficient surround-view world-action model that preserves full six-camera observations while leveraging future-video prediction only as training supervision, enabling efficient action-only planning without future-video rollout at inference.
Education
|
Institute of Automation, Chinese Academy of Sciences M.S. in Pattern Recognition and Intelligent Systems |
2025 — 2028 |
|
University of Science and Technology Beijing B.Eng. in Automation |
2021 — 2025 |
Selected Honors & Awards
- National Second Prize, Chinese Mathematics Competitions for College Students.
- National Second Prize, Siemens Cup China Intelligent Manufacturing Challenge — Team Leader.
- Outstanding Graduate, University of Science and Technology Beijing.